
DeepEval로 LLM/RAG 유닛 테스트하기
DeepEval로 LLM/RAG 유닛 테스트하기 (Unit Testing LLMs/RAG With DeepEval)
DeepEval은 AI 에이전트와 LLM 기반 애플리케이션의 유닛 테스트를 제공해요. RAG 애플리케이션의 답변 품질을 평가하는 간단한 인터페이스를 만들어 봅시다.
출처: 문서
본문
DeepEval은 AI 에이전트와 LLM 기반 애플리케이션을 위한 유닛 테스트를 제공합니다. LlamaIndex 사용자가 LLM 출력에 대한 테스트를 쉽게 작성할 수 있게 해주는 아주 간단한 인터페이스를 제공하며, 개발자가 프로덕션에서 발생하는 치명적인 변경(breaking changes)을 잡아내는 데 도움을 줍니다.
DeepEval은 응답을 측정하는 독자적인(opinionated) 프레임워크를 제공하며 완전히 오픈소스입니다.
설치 및 설정
DeepEval을 추가하는 것은 간단하고 설정이 필요 없습니다. 설치하려면:
터미널 창
pip install -U deepeval
# Optional step: Login to get a nice dashboard for your tests later!
deepeval login
설치가 끝나면 test_rag.py를 만들어 테스트를 작성할 수 있습니다.
test_rag.py
import pytest
from deepeval import assert_test
from deepeval.metrics import AnswerRelevancyMetric
from deepeval.test_case import LLMTestCase


def test_case():
    answer_relevancy_metric = AnswerRelevancyMetric(threshold=0.5)
    test_case = LLMTestCase(
        input="What if these shoes don't fit?",
        # Replace this with the actual output from your LLM application
        actual_output="We offer a 30-day full refund at no extra costs.",
        retrieval_context=[
            "All customers are eligible for a 30 day full refund at no extra costs."
        ],
    )
    assert_test(test_case, [answer_relevancy_metric])
그런 다음 테스트를 이렇게 실행할 수 있습니다.
터미널 창
deepeval test run test_rag.py
로그인되어 있다면 deepeval의 대시보드에서 평가 결과를 분석할 수 있습니다.
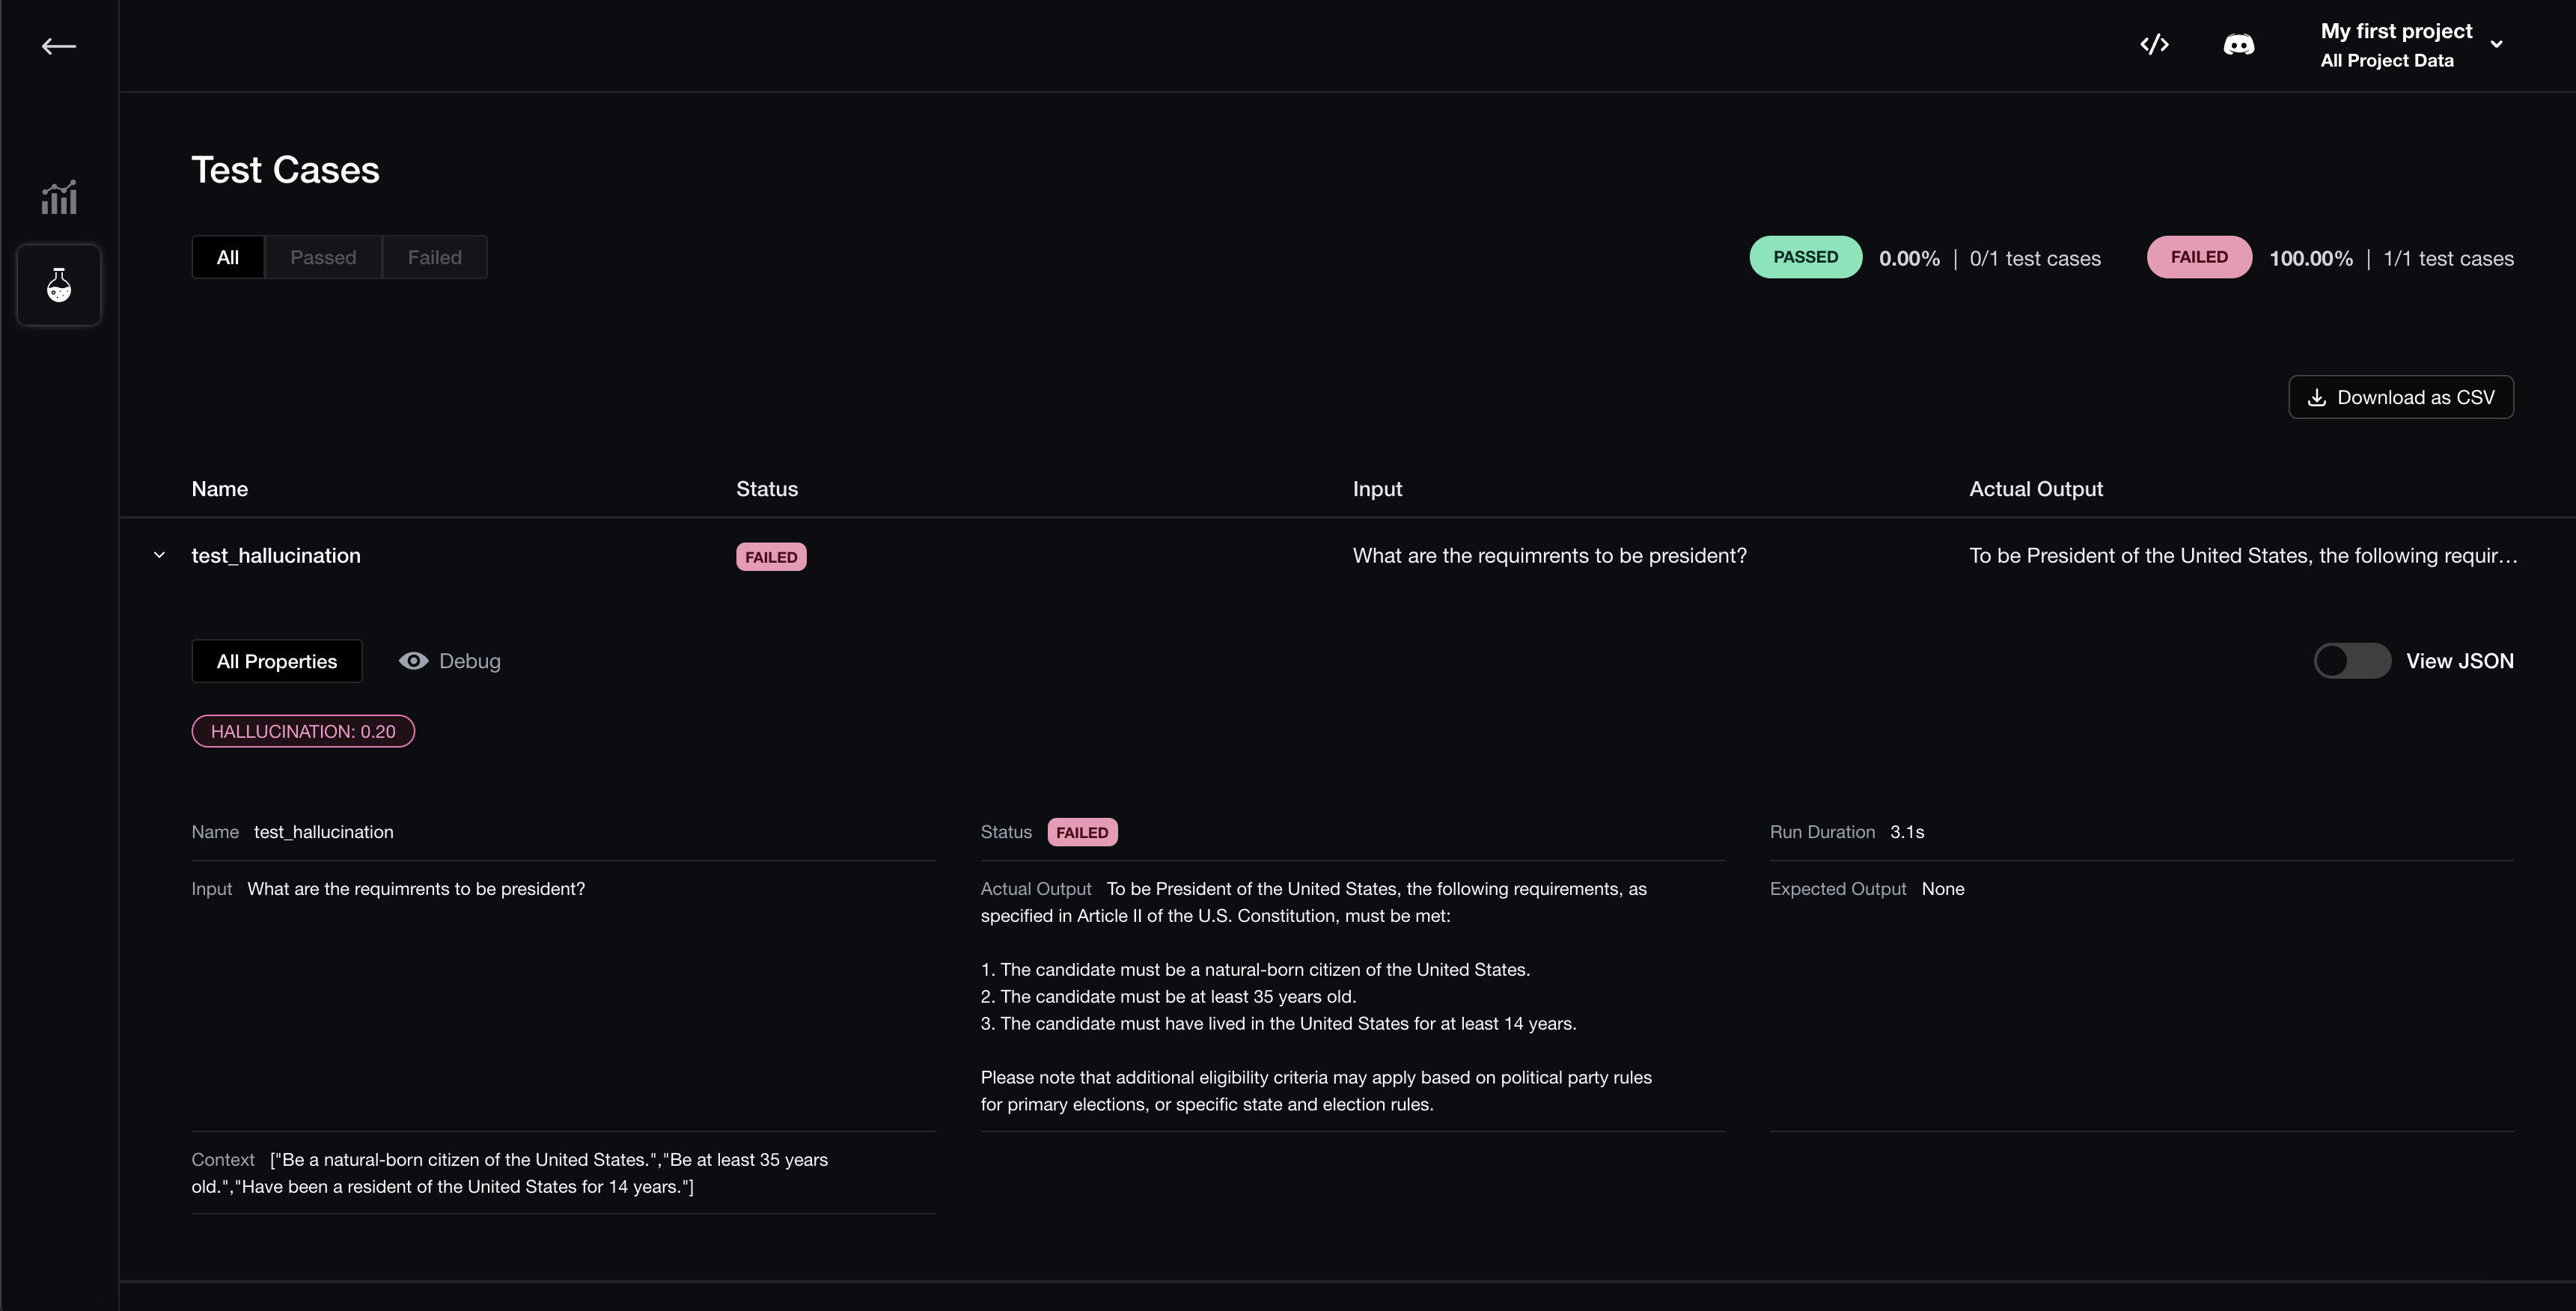
메트릭 종류
DeepEval은 RAG 애플리케이션을 유닛 테스트하기 위한 독자적인 프레임워크를 제공합니다. 평가를 테스트 케이스로 나누고, 각 테스트 케이스마다 자유롭게 평가할 수 있는 다양한 평가 메트릭을 제공합니다:
- G-Eval
- Summarization
- Answer Relevancy
- Faithfulness
- Contextual Recall
- Contextual Precision
- Contextual Relevancy
- RAGAS
- Hallucination
- Bias
- Toxicity
DeepEval은 평가 메트릭에 최신 연구를 반영합니다. 전체 메트릭 목록과 계산 방식에 대한 자세한 내용은 여기에서 확인하세요.
LlamaIndex 애플리케이션의 RAG 평가하기
DeepEval은 LlamaIndex의 BaseEvaluator 클래스와 잘 통합됩니다. 아래는 DeepEval의 평가 메트릭을 LlamaIndex 평가기(evaluator) 형태로 사용하는 예시입니다.
from llama_index.core import VectorStoreIndex, SimpleDirectoryReader
from deepeval.integrations.llama_index import DeepEvalAnswerRelevancyEvaluator


# Read LlamaIndex's quickstart on more details
documents = SimpleDirectoryReader("YOUR_DATA_DIRECTORY").load_data()
index = VectorStoreIndex.from_documents(documents)
rag_application = index.as_query_engine()


# An example input to your RAG application
user_input = "What is LlamaIndex?"


# LlamaIndex returns a response object that contains
# both the output string and retrieved nodes
response_object = rag_application.query(user_input)


evaluator = DeepEvalAnswerRelevancyEvaluator()
그런 다음 이렇게 평가할 수 있습니다.
evaluation_result = evaluator.evaluate_response(
    query=user_input, response=response_object
)
print(evaluation_result)
전체 평가기 목록
deepeval에서 6개의 평가기를 모두 import하는 방법은 다음과 같습니다.
from deepeval.integrations.llama_index import (
    DeepEvalAnswerRelevancyEvaluator,
    DeepEvalFaithfulnessEvaluator,
    DeepEvalContextualRelevancyEvaluator,
    DeepEvalSummarizationEvaluator,
    DeepEvalBiasEvaluator,
    DeepEvalToxicityEvaluator,
)
모든 평가기 정의와 DeepEval의 테스트 스위트와의 통합 방식을 이해하려면 여기를 클릭하세요.